TL;DR

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
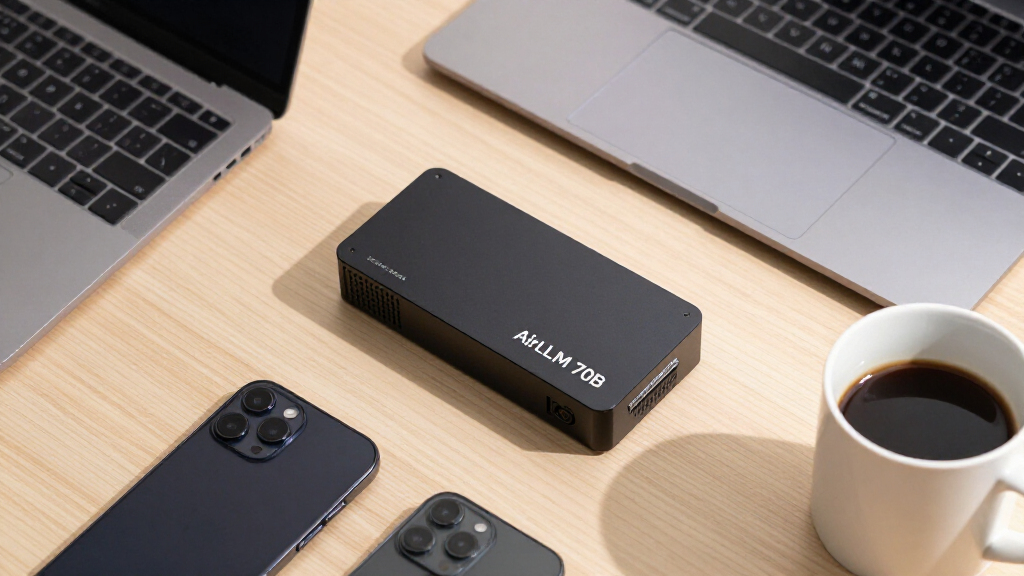
AirLLM has announced successful inference of a 70-billion-parameter language model using only a single 4GB GPU. This development questions traditional hardware constraints for large models. The details are still emerging, but it could impact AI deployment strategies.
AirLLM has announced successful inference of a 70-billion-parameter language model on a single 4GB GPU. This achievement challenges longstanding assumptions about the hardware requirements for large language models and could influence AI deployment practices. The company claims this is possible through novel optimization techniques, though details remain limited.
According to AirLLM, their new approach allows a 70-billion-parameter model to run inference on a single 4GB GPU. This contrasts sharply with conventional wisdom, which typically requires multiple high-memory GPUs or specialized hardware for models of this size. The company did not disclose specific technical methods but emphasized the role of advanced model compression, quantization, and optimized inference algorithms.
Sources familiar with the development suggest that this breakthrough could dramatically reduce the hardware costs and energy consumption associated with deploying large language models. However, it is not yet clear whether this technique supports training or only inference, nor whether it maintains the same accuracy levels as larger hardware setups.
Potential Impact on Large-Scale AI Deployment
This development could significantly lower the barrier to entry for deploying large language models, making them accessible to smaller organizations and individual developers. If validated, it may lead to a shift away from reliance on expensive, specialized hardware, enabling more widespread use of large models in applications like chatbots, content generation, and research.
However, it is important to note that the current claims focus on inference performance; the impact on training, model accuracy, and broader usability remains to be confirmed by independent testing and peer review.
As an affiliate, we earn on qualifying purchases.
Historical Hardware Requirements for Large Language Models
Traditionally, large language models like GPT-3 (175B parameters) require multiple high-memory GPUs or specialized hardware clusters for inference and training, often costing millions of dollars. Recent advances in model compression, quantization, and distributed computing have gradually reduced hardware demands, but running a 70-billion-parameter model on a single 4GB GPU remains unprecedented.
Previous efforts have demonstrated smaller models or relied on offloading parts of the model across multiple devices. AirLLM’s claim, if validated, could represent a paradigm shift in how large models are optimized for resource-constrained environments.
Technical Details and Validation Still Unclear
It is not yet clear how the model maintains accuracy and inference speed comparable to larger hardware setups. The specific techniques used for compression and optimization have not been publicly detailed. Independent testing and peer review are pending, so the claims remain preliminary.
Independent Testing and Broader Adoption Expected Soon
Further validation by third-party researchers and AI practitioners is anticipated. If the results are confirmed, expect increased interest in low-resource AI deployment and potential integration into commercial products. AirLLM may also release more technical details or open-source tools to support adoption.
Key Questions
Can this technique be used for training large models?
Currently, the claims focus on inference. It is unclear whether the same methods can be applied to training large models, which typically require more resources.
Does this impact the accuracy of the model?
AirLLM has not yet provided detailed performance metrics or accuracy comparisons. Validation is needed to determine if the compressed model retains original capabilities.
What hardware is needed to replicate this setup?
According to the announcement, only a single 4GB GPU is required, but specifics about the GPU model or additional hardware are not yet disclosed.
Will this approach be available for public use?
It remains to be seen whether AirLLM will release technical details, open-source tools, or commercial products based on this breakthrough.
How does this compare to existing model compression techniques?
This approach appears to go beyond traditional compression by enabling large-scale inference on minimal hardware, but detailed comparisons are not yet available.
Source: hn
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.