TL;DR
Open a free Amazon Business account
Business pricing, bulk buying and tax-exempt orders.
Create a free accountAs an affiliate, we earn on qualifying purchases.
Researchers have unveiled vLLM, a novel system designed for high-throughput inference of large language models in 2025. This development promises faster, more efficient AI deployment but leaves questions about scalability and integration.
Researchers introduced vLLM, a new system designed for high-throughput inference of large language models (LLMs) in 2025. The system aims to significantly increase processing speed and efficiency, addressing longstanding bottlenecks in deploying large models at scale.
vLLM employs a novel architecture that combines optimized memory management, parallel processing, and dynamic batching to achieve higher throughput. According to the developers, this system can handle multiple large models simultaneously, reducing latency and increasing throughput by up to 3x compared to existing solutions.
Developed by a team of AI engineers and researchers, vLLM integrates with popular machine learning frameworks and is designed to be scalable across different hardware setups, from single GPUs to large clusters. The team claims it can support real-time applications such as chatbots, virtual assistants, and large-scale AI services.
Initial benchmarks, shared in the official release, suggest vLLM can process over 10,000 tokens per second per GPU, a notable improvement over previous inference engines. The developers also highlight its ability to dynamically allocate resources based on workload, optimizing hardware utilization.
Potential Impact on AI Deployment and Scalability
The introduction of vLLM marks a significant step toward making large language models more practical for real-world applications. By greatly increasing inference throughput, it could reduce operational costs and enable more responsive AI services. This development is particularly relevant for industries relying on real-time AI interactions, such as customer support, content moderation, and virtual assistants.
Moreover, the system’s scalability could facilitate broader adoption of large models in smaller organizations and edge devices, democratizing access to advanced AI capabilities. However, the actual impact depends on how well vLLM integrates with existing infrastructure and whether it can maintain performance at larger scales.
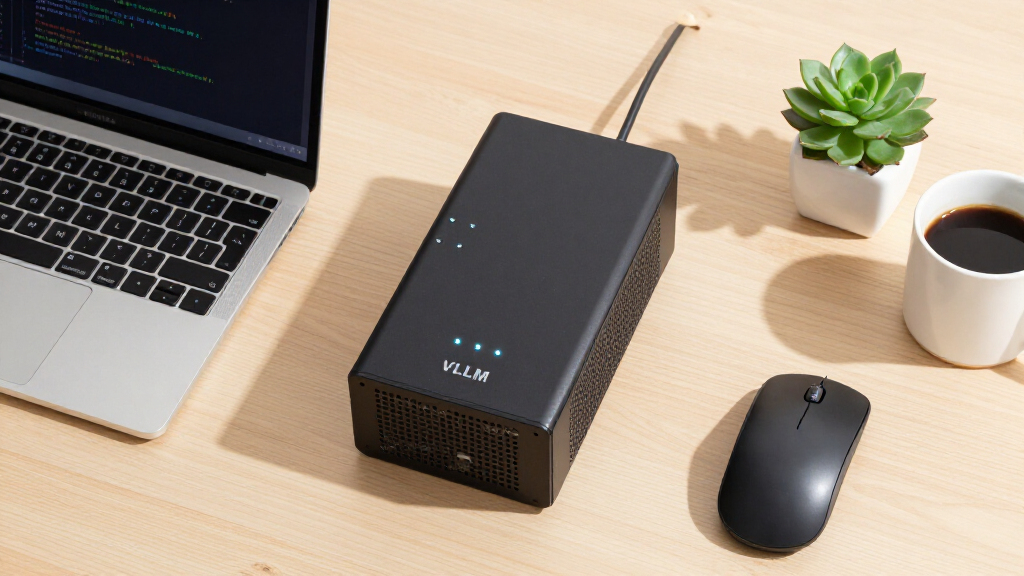
high performance GPU for AI inference
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Advances in LLM Inference Systems in 2025
Over the past few years, the AI community has focused on improving the efficiency of large language model inference, with solutions like model quantization, pruning, and specialized hardware. In early 2025, several companies and research groups announced efforts to push these boundaries further, emphasizing throughput and cost reduction.
Prior to vLLM, systems like FasterTransformer and Triton Inference Server made strides in optimizing GPU utilization but still faced challenges with latency and resource management at scale. vLLM’s architecture builds upon these efforts, introducing a modular design that emphasizes dynamic resource allocation and parallel processing.
The release of vLLM coincides with increased industry demand for scalable, real-time AI services, especially as large models become more prevalent in commercial applications.
Unanswered Questions About vLLM’s Scalability and Integration
While vLLM’s initial benchmarks are promising, it is still unclear how well the system performs across different hardware environments and larger-scale deployments. Details about its compatibility with various cloud platforms and edge devices remain limited, and real-world testing results are yet to be published.
Additionally, questions about how vLLM manages model updates, security, and long-term stability are still open, as the system is in early adoption phases.
Next Steps for vLLM Adoption and Evaluation
Expect further benchmarking reports and case studies from early adopters over the coming months. Developers are likely to release updates aimed at improving compatibility, security, and ease of integration. Industry analysts will monitor its performance in diverse environments, potentially influencing wider adoption.
Research teams may also explore extending vLLM’s architecture to support emerging AI models and hardware platforms, further testing its scalability and robustness.
Key Questions
What makes vLLM different from previous inference systems?
vLLM employs a novel architecture that combines optimized memory management, dynamic batching, and parallel processing to achieve higher throughput and lower latency compared to earlier systems like FasterTransformer.
Can vLLM support real-time AI applications?
Initial benchmarks suggest it can process over 10,000 tokens per second per GPU, making it suitable for real-time applications such as chatbots and virtual assistants, though broader testing is ongoing.
Is vLLM compatible with existing AI frameworks?
Yes, the developers have designed vLLM to integrate with popular frameworks such as PyTorch and TensorFlow, with plans to expand compatibility.
What are the main limitations of vLLM at this stage?
Its performance across diverse hardware environments and long-term stability are still being evaluated. Details on security and model update management are also pending.
When will vLLM be widely available?
Early versions are currently in testing with select partners. Full commercial availability is expected later in 2025, following further validation and development.
Source: hn
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.